

Modern software engineering gives us a set of practices that we tend to
carry from one project to another: AI assisted development, automated
testing, CI/CD, observability, automation, simulation, and safe deployment.
They work well enough that we sometimes forget to question the assumptions
behind them.
I had to question some of those assumptions when our team started
modernizing a large retail IoT system. The system had around 800,000
battery-powered sensors deployed across 3000 stores. The existing
connectivity technology was reaching the end of its life, and we needed to
move to a newer technology without replacing the installed devices, and also
onboard newer stores with next gen devices.
Our team knew software engineering well. We had experience with web
applications, cloud platforms, mobile applications, IoT and other
distributed systems. What we did not have was deep experience in embedded
firmware and large-scale device networks. We thought the software
engineering skills would apply here too, and it did, the engineering
principles remain the same, but the default practices
changed.
Let us find how we discover this change.
Learn by building an experimentation environment
After initial spikes on firmware development technology, our challenge was
no more writing the firmware, but actually to understand the IOT system that
has been running for years, as the organizational changes had left gaps in the
knowledge of the existing firmware, hardware and network architecture.
Documentation helped, but it wasn’t enough. Things weren’t documented, and
some documents described hardware or behaviour we couldn’t reproduce. Some
answers could only be found by putting our hands on the actual devices, and
playing with limited access to production systems.
So we started building things and measuring what actually happened. We
built an IoT lab with physical sensors, wire harnesses and learning kits. We
created environments where we could experiment with radio behaviour, reused
sensors with dead batteries for testing, and measured power consumption and
network behaviour.
All these initially looked like our preparation, trials but quickly all
this started becoming our engineering work, and soon we were not waiting to
understand the system. The IOT lab became part of how we learned, and reverse
engineered.
For embedded systems, sometimes the fastest way to answer a question is not
to read another document, but to connect the device and see what happens.
Consider the physical world part of the development lifecycle
In conventional software, the development environment is usually made up
of software tools. A developer can clone a repository, install dependencies
and run the application irrespective of physical location, working from
anywhere.
The equivalent setup for our project needed something else. It needed
physical devices. We end up creating what we called a sensor farm: a
controlled collection of real devices connected to the new network, with
monitoring around them. This enabled our engineers to work with multiple
devices and observe what happened when they communicated, slept, woke up or
lost connectivity. Physical placement, radio conditions and power, all became
part of development and testing.
We didn’t need every developer to have a laboratory on their desk, but we
did need the development process to provide access to the physical behaviour
of the system and get fast feedback, the engineering practices like TDD,
Automation, XP were all applicable but with hardware in
loop.
Every device must be able to explain itself
Once we had a working device, well integrated as part of the
development environment, another question appeared: “What happens when the
device is somewhere we cannot reach?” This sounds like an operational
question, but it turned out to be an architectural one.
Imagine an engineer receives a report that a sensor isn’t behaving
correctly. The sensor is sitting in a store or development environment,
and the engineer is somewhere else. In this case there is no debugger
attached, there may be no one available to open the device, the device may
be asleep, and the network may not even be available.
A conventional application can often tell us what happened through logs
and traces, but a physical device doesn’t automatically have that
capability. We therefore started building diagnostics into the device
firmware itself, where we wanted to know things like which firmware was
running, whether the device was healthy, when it last communicated, what
its network state was, what happened before a failure, whether it was
sleeping, whether it was repeatedly reconnecting, and what its firmware upgrade
status was.
We added health checks and diagnostic information, ways to access that
information locally, and APIs so that the same information could be
retrieved remotely. We then started feeding the information into
dashboards and operational tooling.
This changed the way we thought about observability. We weren’t simply
adding logging to an application. We were designing a system that could
operate devices we could not physically see, where each device needed to explain itself. For a small number of
devices, this is useful. For hundreds of thousands, it becomes
essential.
Design interfaces for engineers as deliberately as interfaces for users.
Diagnostics solved only part of the problem. Engineers also needed
ways to interact with the device without physically opening it.
We needed local interfaces such as NFC and BLE, as well as remote
interfaces through the gateway and platform. These allowed engineers to
inspect configuration, retrieve diagnostics, understand device state and
perform operations remotely.
This made us think differently about engineering interfaces. We
normally spend a lot of time designing interfaces for users, while
interfaces for engineers and operators can become an afterthought.
For a large device fleet, they are part of the system.
Simulate what is expensive to reproduce physically
The next surprise came when we increased the number of devices, and
reached the real store.
Everything was fine, until we onboarded a handful of devices,
onboarded smaller stores, but as we moved to larger stores, the
network infrastructure had limits we had not encountered during
smaller lab experiments. At one point, we discovered that the new network
hardware could support only a limited number of devices—far below the
scale required by some larger stores.
Testing a few devices is very different from testing thousands.
Network behavior, infrastructure limits, message rates, device
physical location constraints and device disconnection problems
started appearing at scales that were difficult to reproduce
physically.
So we built a virtual device emulator: special firmware for the
same device that could simulate hundreds of unique devices, each
can be configured behave differently under different network and environmental
conditions. Running many of these virtual devices together allowed us
to simulate a large store environment and test the parts of the system
where scale itself was the problem. This did not replace physical
testing. We still needed real devices to validate firmware, hardware
and radio behavior.
We also built a virtual store that behaved like a real store, with
a gateway publishing simulated sensor readings to the platform. This
allowed us to exercise the downstream systems at store scale without
needing hundreds of physical devices for every test.
Design for disconnection, not just connection.
Enterprise applications often make a comfortable assumption: the network is
available, and it is considered an infrastructure concern, and applications
need to make sure it handles disconnection with a good user-friendly way,
letting application reconnect immediately.
A battery-powered device has a different relationship with the
network.
The device may sleep on idle to save battery, It may temporarily lose
connectivity. It may reconnect repeatedly. It may not be reachable at the
exact moment the platform wants to communicate with it. Remember that a
connection attempt is the heaviest operation for the device.
We therefore had to carefully design for intermittent connectivity
rather than treating it as an exceptional failure. This affected firmware,
gateway communication, commands, telemetry and device management. Once we
accepted that the device would sometimes be unavailable, many design
decisions became clearer.
Treat energy consumption as a software design concern.
There was another constraint that was easy to underestimate: the device had
a limited amount of energy, but it is supposed to be operational for
years.
In a server application, an inefficient operation might consume more CPU,
memory or increase cloud cost. In a battery-powered sensor, unnecessary
computation or communication can reduce the useful life of the device.
We introduced power measurement and profiling into our development process.
We looked at when the device was awake, how often it communicated and what
different operations meant for battery consumption.
The important thing wasn’t simply optimizing the code. It was understanding
that every design decision could have a physical consequence—even
something as small as a log statement or a few lines of code that appeared to
be unused.
We also had to rethink some of our usual assumptions about memory
management. Instead of aggressively cleaning up allocated memory after every
operation, in some cases we chose a simpler approach: let the device run for
24 hours and then reboot it as part of its normal operating cycle.
On a device, sometimes the simplest software solution is not the one we
would choose in a server.
Design deployment and recovery together.
Firmware deployment introduced another challenge.
A cloud application can often be rolled back quickly when something goes
wrong. Physical devices distributed across thousands of stores does not give
us that luxury.
The battery consumed in downloading and installing firmware can not be
rolled back. The device might be offline during an update. The network might
fail halfway through a download. The firmware might not validate correctly.
Or a problem might only become visible after deployment. All this would
change the meaning of deployment and recovery.
We therefore designed firmware updates with recovery as part of the
deployment mechanism. We implemented over the air firmware updates using
secure downloads, validation and partition swapping. Updates could be
applied to individual devices, groups of devices or stores, with progress
visible through the gateway and, where useful, locally through NFC. The
device also stored its firmware upgrade state, allowing an update to resume
from where it left off after recovering from an interruption or failure.
More importantly, we designed a staged rollout, as we wanted to know what
happened after an update before updating everything. After all, the question
was no longer just, “How do we deploy the new firmware?” but, “How do we
deploy it safely, and what happens when it goes wrong?”
Optimize the engineering process for confidence at scale.
By this point, something subtle had changed.
Early in the project, we talked like software engineers. How quickly
can we build this? How quickly can we deploy it? How automated can we make
the pipeline?
Those questions still mattered. But increasingly, our conversations
became different. Can we trust this firmware update? Can we recover if
something goes wrong? Can we explain why this device failed? Can we
understand what is happening across a store? Can we safely update
thousands of devices? What will this do to battery life? And how long will
it take to upgrade a store?
We were optimizing for something slightly different: confidence.
That didn’t mean giving up speed. It meant recognizing that speed without
confidence isn’t necessarily progress. For a physical fleet, a fast
deployment that creates thousands of unhealthy devices is a very efficient
way to create a large problem.
Design observability for the fleet, not just the device.
Making an individual device explain itself was necessary, but it was
not sufficient. With hundreds of thousands of devices, nobody can
inspect them one by one. The question changed from “What is this device
doing?” to “What is happening across the fleet?”
We built dashboards and analytics to identify communication failures,
unusual behavior, outages, firmware distribution, patterns and other
fleet-level conditions. Operational teams needed alerts and tools that
could show whether a problem was isolated or affecting a much larger
part of the fleet.
The engineering environment became part of the system
By this point, several things that had started as engineering or
operational tools had become essential parts of the overall
system.
The physical sensor farm helped us learn and test. The virtual
device emulator helped us test at scale. Diagnostic interfaces allowed
engineers to understand devices remotely. The gateway provided
communication and management capabilities. Dashboards and analytics
allowed operations teams to understand the fleet.
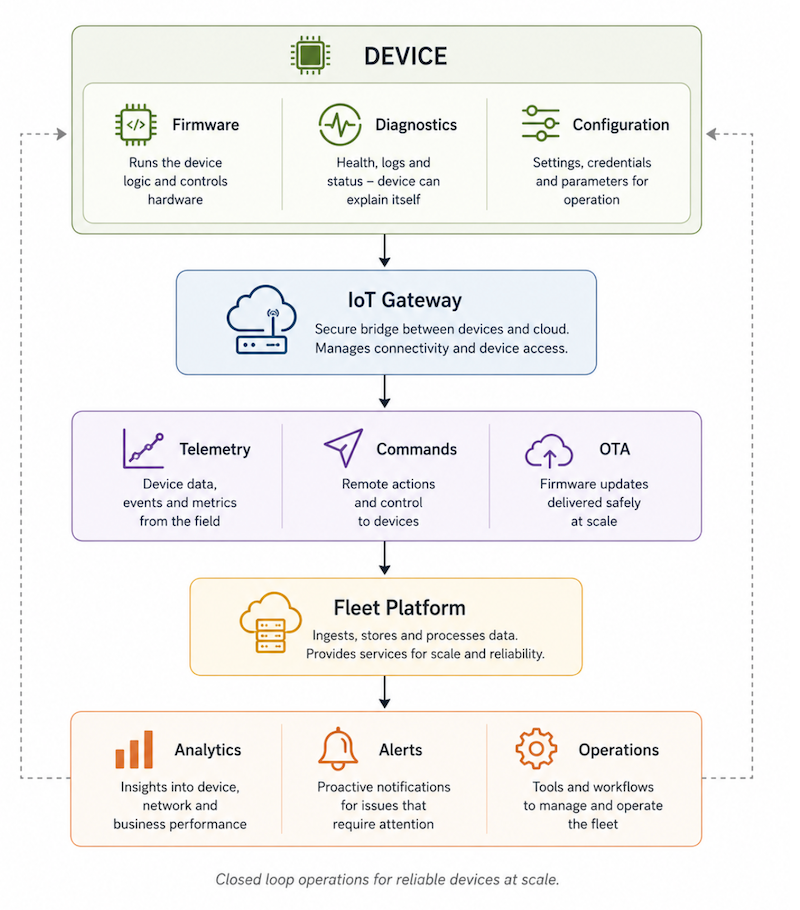
The architecture started looking something like this:
Device → Firmware, Diagnostics and Configuration → IoT Gateway →
Telemetry, Commands and OTA → Fleet Platform → Analytics, Alerts and
Operations
Figure 1: An engineering environment: Hardware, Software, and Feedback
These were not simply developer conveniences. Together they allowed us
to build, test, operate, migrate and manage a very large physical fleet.
The more devices we had, the more valuable this surrounding platform
became.
Use AI to shorten the learning loop, not just the coding loop.
AI also became part of how we worked, although not in the way we
initially expected.
We used LLMs to explore unfamiliar areas, prototype solutions and
shorten the time between a question and a useful experiment. We also
used AI-assisted development to build dashboards, migration
trackers, outage detection and other engineering tools more
quickly.
The important benefit was not simply generating code. It was
reducing the cost of trying something.
Capture discoveries, not just decisions.
We were learning through experiments, failures, measurements
and operational incidents. If we did not capture those
discoveries, the next person would have to learn the same lesson
again.
Documentation therefore became more than recording architecture
decisions. We captured what we had learned about devices,
networks, testing, diagnostics, deployment and operations, and
shared that learning through technical articles, training and our
engineering community.
Traditional documentation often tells us what the system is. In
an unfamiliar domain, it is equally valuable to capture how we
discovered why it is that way.
The principles stayed, the defaults changed
Looking back, I don’t think we invented a new methodology for IoT or embedded
software.
We still wanted fast feedback, automation, good testing, observability,
maintainability, safe deployment and continuous learning. What changed was how
those principles were practiced.
Over time, the changes looked like a new set of defaults.
| We started with this assumption | We ended up with this sensible default |
|---|---|
| Documentation should tell us enough | Learn by building an experimentation environment |
| Hardware can be tested later | Consider the physical world part of the development lifecycle |
| A device performs its function, and platform can always explain its health | Every device must be able to explain itself |
| Interfaces are primarily for users | Design interfaces for engineers as deliberately as interfaces for users |
| Network behavior, physical environment can be tested and reproduced with a few devices in lab | Simulate what is expensive to reproduce physically |
| Devices should normally be reachable | Design for disconnection, not just connection |
| Battery is mainly a hardware concern | Treat energy consumption as a software design concern |
| Deployment means installing firmware | Design deployment and recovery together |
| Optimize primarily for delivery speed | Optimize the engineering process for confidence at scale |
| Observability means logs and metrics | Design observability for the fleet, not just the device |
| Build the product, then supporting tools | The engineering environment became part of the system |
| AI helps write code | Use AI to shorten the learning loop, not just the coding loop |
| Discovery happens before development and capture decisions in the final design | Capture discoveries, not just decisions |
The table is a record of what happened. Each default was earned by
encountering a problem.
Why call them sensible defaults?
I use the term sensible defaults deliberately.
None of these practices was invented from first principles. Most emerged
from problems we encountered. We started with an assumption that seemed
reasonable, ran into something that challenged it, experimented, and gradually
changed the way we worked.
That is how engineering practices often evolve in real projects. The
environment tells you where your assumptions are wrong. If you pay attention,
those failures can help you discover a better default.
That was certainly our experience. When software meets hardware, the
engineering principles do not necessarily change. But the sensible defaults
might.